
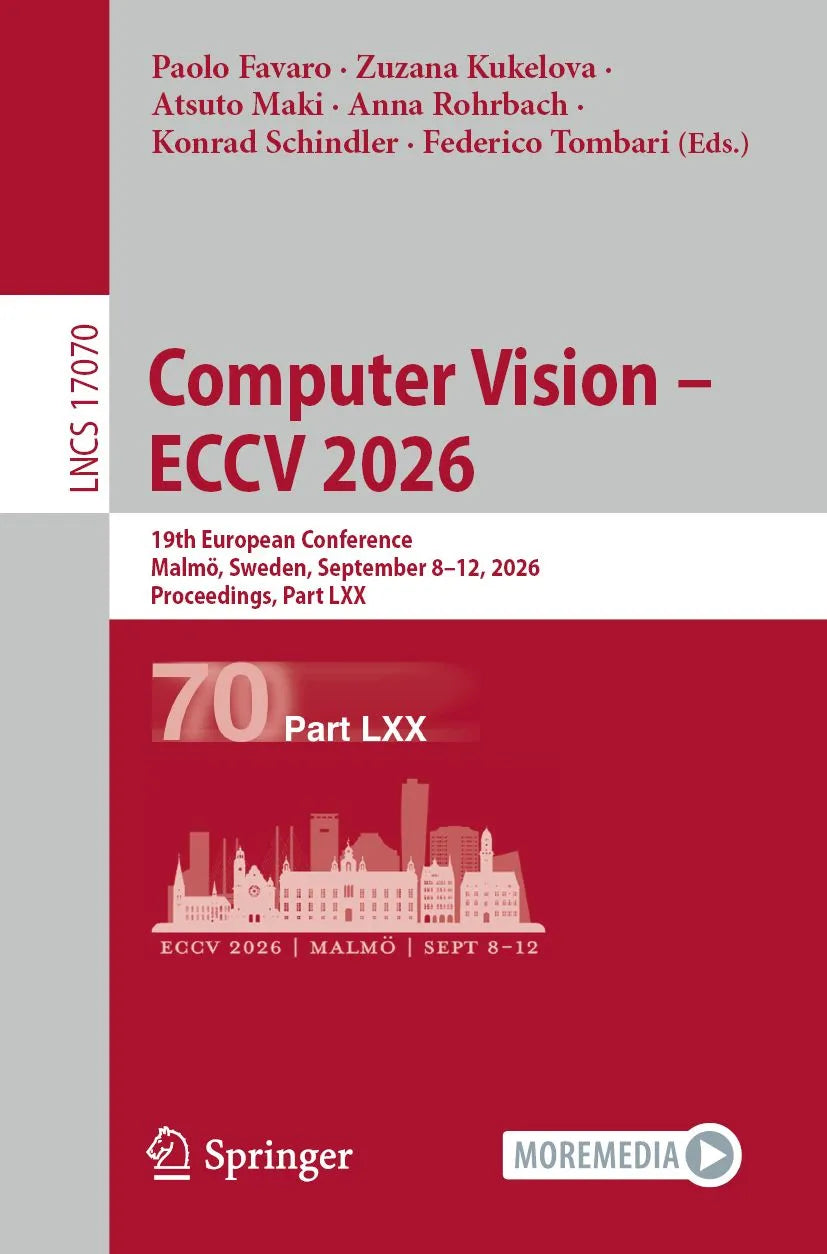
Teil der Reihe: Springer Nature Proceedings Computer Science
Computer Vision - ECCV 2026
Inhaltsangabe
LinStereo: Linear-Complexity Global Attention for Multi-Scale Iterative Stereo Matching.- EMOTE: Expressive Motion and Shape Disentanglement for Human Animation.- SCoT: Similarity-guided Conflict-aware Task Consolidation for Continual VQA.- FixAnything: 3D-Consistent Rendering Refinement via Video Generative Priors.- Solving Diffusion Inverse Problems with Restart Posterior Sampling.- JointHOI: Jointly Generating Contact Maps Enhances Hand Object Interaction Generation.- Thermo-JEPA: Learning a Geometry-Grounded Thermal World Model via Cross-Modal Privileged Masking.- Enhancing Embodied Reasoning and Grounding by Novel View Synthesis.- Robust 3DGS-based SLAM via Adaptive Kernel Smoothing.- AVQ-Attention: Adaptive Vector-Quantized Attention.- Aligning Human Sense: Calibrated Distributional Reward Learning for Video Generation.- ReasonCLIP-58M: Visually Grounded Commonsense Reasoning Supervision for CLIP.- LaMP: Learning Vision-Language-Action Policies with 3D Scene Flow as Latent Motion Prior.- VOID: Video Object and Interaction Deletion.- Natural Language Camera Movement Understanding.- MuCHeR: Multi-Person Camera-Centric Human Detection, Mesh Recovery and Tracking.- SA-ResGS: Self-Augmented Residual 3D Gaussian Splatting for Next Best View Selection.- Policy-Based Tuning of Autoregressive Image Models with Instance- and Distribution-Level Rewards.- Unified Prediction and Planning via Conflict-Aware Disjoint Parameter Training.- Fast-dVLA: Accelerating Discrete Diffusion VLA to Real-Time Performance.- CL-Anomaly: Layer-Adaptive Mixture-of-Experts with Multimodal Large Language Model for Continual Learning in Anomaly Detection.- GridVQA-X: A Diagnostic Framework for Evaluating Multimodal Explainability Methods.- WildProp: Visual Estimation of Wildlife Body Proportions at Scale.- DriveWeaver: Point-Conditioned Video Inpainting for Controllable Vehicle Insertion in Autonomous Driving Simulation.- OpenGround: Planning-based Online Perception for Open-World 3D Visual Grounding.- WeEdit: A Dataset, Benchmark and Glyph-Guided Framework for Text-centric Image Editing.- TDSR-VLA: Transition-aware Denoising Sequence Representations for Vision-Language-Action.- RelAfford6D: Relational 6D Affordance Graphs for Constraint-Driven Robotic Manipulation.- From Script to Shot: A Benchmark for Grounding Screenplays in Movies.- GeoNVS: Geometry Grounded Video Diffusion for Novel View Synthesis.- TETO: Tracking Events with Teacher Observation for Motion Estimation and Frame Interpolation.- Weight Feedback Computes the Exact Jacobian Transpose in Modern Deep Networks.- CogniCred: A Dataset and Benchmark for Cognitive Credential Forgery Detection.- JacobianAvatar: Temporally Consistent Semi-rigid Avatar Reconstruction from a Monocular Video.- LEGO: Leveled Language Gaussian Splatting.- MobileOcc: A Human-Aware Semantic Occupancy Dataset for Mobile Robots.
Produktdetails
- Erscheinungsdatum: 10.09.2026
- Autor/Autorin: Paolo Favaro
- Format: E-Book
- Dateiformat: PDF
- Kopierschutz: Wasserzeichen
- Dateigröße: 189.6 MB
- Verlag: SPRINGER
- Sprache: Englisch
- Umfang: 701 Seiten
- ISBN: 9783032370136
- Lieferung: Sofort per Download
- Hinweis: Sofort per Download lieferbar. Kein physischer Versand.
- Kompatibilität: Lesbar auf Geräten und Apps mit PDF-Unterstützung.
Herstellerinformationen
Email: ProductSafety@springernature.com