
Teil der Reihe: Springer Nature Proceedings Computer Science
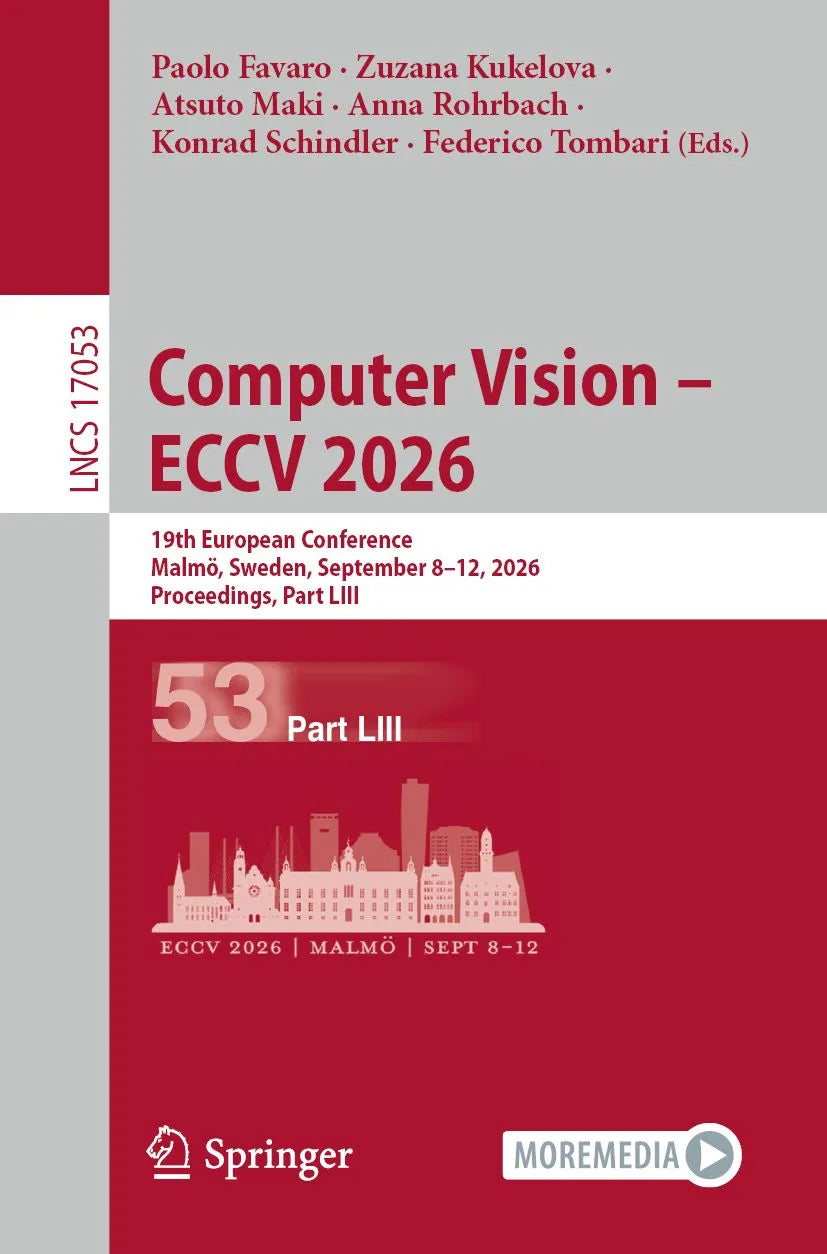
Computer Vision - ECCV 2026
Inhaltsangabe
SGP2: Coarse-to-Fine Controllable Multimodal Remote Sensing Image Generation.- Tiled Prompts: Overcoming Prompt Misguidance in Image and Video Super-Resolution.- GameWorlds: Towards Standardized and Verifiable Evaluation of Multimodal Game Agents.- InSpace: Structure-Aware 3D Indoor Scene Generation from a Single 360° Image.- Video Streaming Thinking: VideoLLMs Can Watch and Think Simultaneously.- DIVER: Disentangling Camera–Object and Active–Passive Motion for Video Generation.- Text-Conditioned Background Generation for Editable Multi-Layer Documents.- VoCa: Unified Autoregressive Modeling for Talking Audio-Video Generation.- Decompose, Compare, and Decide: Multimodal LLMs are Implicit Few-Shot Learners.- NarrativeTrack: Evaluating Entity-Centric Reasoning for Narrative Understanding.- Hi-DiT: Hybrid Latent-Pixel Diffusion Transformer for Image Generation.- Cube-Splat: High-Fidelity 360° Gaussian Splatting SLAM via Cubemap Factorization and Adjoint-Consistent Optimization.- Motion-aware Sparse Pipeline for Lightweight Object Tracking.- VideoTIR: Accurate Understanding for Long Videos with Efficient Tool-Integrated Reasoning.- Face Anything: 4D Face Reconstruction from Any Image Sequence.- ReDesign: Recovering Editable Design Structures from Raster Images via Agentic Decomposition.- Distill on a Diet: Efficient Knowledge Distillation via Learnable Data Pruning.- SPAR: Semantic-Pixel Self-Alignment and Adaptive Routing for Unified Multimodal Models.- VoxAnchor: Explicit Voxel-Semantic Grounding for Spatial Understanding in Videos.- LISA: Locality-Informed Speculative Decoding for Accelerating Autoregressive Image Generation.- Layering Virtual Try-On.- clean2green2clean: Synthesising Bad Composites to Learn Actor-Background Video Harmonisation.- EatVid-Bench: A Multimodal Fine-Grained Eating Behavior Video Dataset.- EAGS: Error-Aware Gaussian Splatting with Dual-Confidence-Guided Modeling for Uncalibrated Driving Scenes.- What Images Cannot Say: Language-Guided Olfactory Representation Learning.- PAI-Studio: Cinematic Video Background Replacement with Camera-Aware Motion.- Multi-modal Knowledge Preserving Adapter for Embedding Backward Compatibility.- Sparse-View Surface Reconstruction using Gaussian Splatting through High-Confidence Depth Propagation with Normal Priors.- Reasoning Path and Latent State Analysis for Multi-view Visual Spatial Reasoning: A Cognitive Science Perspective.- Calibrate Before Adapt: Training-Free Pseudo-Label Calibration for Semi-Supervised Cross-Domain Few-Shot Detection.- Atlas is Your Perfect Context: One-Shot Customization for Generalizable Foundational Medical Image Segmentation.- ICLAgent: Integrated Circuit Footprint Geometry Labeling via LMM-empowered Multi-Agent Framework.- Frozen CLIP Priors for Robust Self-Supervised Poisson Inverse Problems.- CurveStream: Boosting Streaming Video Understanding in MLLMs via Curvature-Aware Hierarchical Visual Memory Management.- 3D Field of Junctions: A Noise-Robust, Training-Free Structural Prior for Volumetric Inverse Problems.- Token-level Response-visual Attention Guidance for Multimodal LLMs Knowledge Distillation.- Benchmarking MLLMs on Mistake Recognition and Explanation in Single-Step Components of Cooking.
Produktdetails
- Erscheinungsdatum: 14.09.2026
- Autor/Autorin: Paolo Favaro
- Format: E-Book
- Dateiformat: PDF
- Kopierschutz: Wasserzeichen
- Dateigröße: 162.2 MB
- Verlag: SPRINGER
- Sprache: Englisch
- Umfang: 681 Seiten
- ISBN: 9783032372550
- Lieferung: Sofort per Download
- Hinweis: Sofort per Download lieferbar. Kein physischer Versand.
- Kompatibilität: Lesbar auf Geräten und Apps mit PDF-Unterstützung.
Herstellerinformationen
Email: ProductSafety@springernature.com