
Teil der Reihe: Springer Nature Proceedings Computer Science
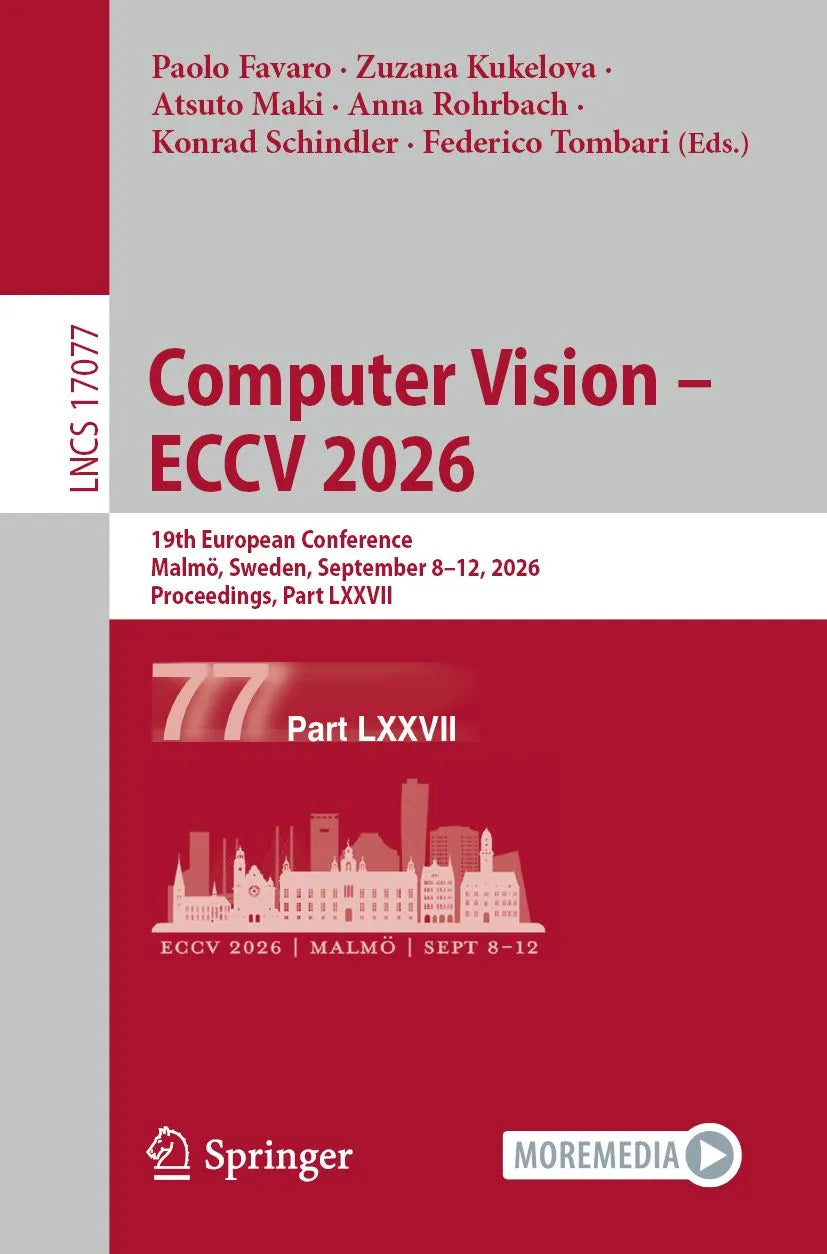
Computer Vision - ECCV 2026
Inhaltsangabe
SIGNET: Motion-Level Knowledge Transfer for Cross-Language Sign Language Translation.- From Draft to Draft-Free: One-Step Video Object Removal via Privileged Distillation and Fast Planting.- Multi-View Foundation Models.- MambaRaw: Selective State Space Modeling for Efficient 4K RAW Image Reconstruction.- Unified Multi-Layer Subspace Modeling for Cross-Domain OOD Detection.- Exo2EgoPolicy: Pose-Aligned Cross-View Policy Learning.- PanoLess: Environment Reconstruction from Partial Reflective Views.- Score-Based Matching with Target Guidance for Cryo-EM Denoising.- Score-Based Matching with Target Guidance for Cryo-EM Denoising.- PhysChoreo: Physics-Controllable Video Generation with Part-Aware Semantic Grounding.- Large-Scale Light Field Synthesis from Videos Enables Geometrically Consistent Bokeh Editing.- TAIHRI: Task-Aware 3D Human Keypoints Localization for Close-Range Human-Robot Interaction.- TEX-Drive: Temporal Perception Meets Experience-Guided Mixture-of-Experts for End-to-End Autonomous Driving.- MixGRPO: Unlocking Flow-based GRPO Efficiency with Mixed ODE-SDE.- ConsiSpace: Learning Geometric Consistency Matters for Video Spatial Reasoning.- CS-TTA: Preserving Concept Sensitivity in Test-Time Adaptation.- FED-Bench: A Cross-Granular Benchmark for Disentangled Evaluation of Facial Expression Editing.- Align and Segment: Unsupervised Learning for Building Segmentation From Misaligned Labels.- Matryoshka Gaussian Splatting.- BlenderFusion: 3D-Grounded Visual Editing and Generative Compositing.- AerialMetric: Benchmarking and Adapting UAV Monocular Metric Depth Estimation in the Real World.- Finding Highlight Images In Your Albums:From Benchmark To MLLM.- Anchor Forcing: Anchor Memory and Tri-Region RoPE for Interactive Streaming Video Diffusion.- MAGiSt3R: Multi-Agent Feed-forward 3D Reconstruction from Monocular RGB Videos.- Dual-Anchoring: Addressing State Drift in Vision-Language Navigation.- DSeq-JEPA: Discriminative Sequential Joint-Embedding Predictive Architecture.- Mitigating Pose–Scale Discrepancy Bias and Reforming Multi-Support Reasoning for Few-Shot Semantic Segmentation.- Beyond Aesthetics: Quantifying Information Loss in Turbid Scenes.- Physics-Guided Deep Learning for Linear Mueller Matrix Acquisition.- Physically Grounded Monocular Depth via Nanophotonic Wavefront Encoding.- What You Ask is What You Ground: Bridging Question Intent to Temporal Evidence for Grounded VideoQA.- Incentive Noise and Structural Prior Infusion for Multi-Modal Object Re-Identification.- Mitigating Radar-Inertial Calibration Ambiguities via SO(3) Manifold Steering.- Adversarial Attack and Disturbance Detection by Hadamard-Coded Output Representations for Object Detection and Semantic Segmentation.- AlignMorph: Tuning-Free Diffusion Image Morphing via Explicit Semantic Transport.- RL from Physical Feedback: Aligning Large Motion Models with Humanoid Control.- UMO: Unified In-Context Learning Unlocks Motion Foundation Model Priors.- SA-V2V: Training-Free Subject-Aware Video-to-Video Personalization.
Produktdetails
- Erscheinungsdatum: 09.09.2026
- Autor/Autorin: Paolo Favaro
- Format: E-Book
- Dateiformat: PDF
- Kopierschutz: Wasserzeichen
- Dateigröße: 174.6 MB
- Verlag: SPRINGER
- Sprache: Englisch
- Umfang: 627 Seiten
- ISBN: 9783032370419
- Lieferung: Sofort per Download
- Hinweis: Sofort per Download lieferbar. Kein physischer Versand.
- Kompatibilität: Lesbar auf Geräten und Apps mit PDF-Unterstützung.
Herstellerinformationen
Email: ProductSafety@springernature.com